Portrait of Kim Dongjin

Kim Dongjin
김동진

AI Researcher
Integrated M.S.–Ph.D. Student
KAIST AI · DAVIAN Lab

Download CV

Kim Dongjin

I am an integrated M.S.–Ph.D. student in the DAVIAN Lab at KAIST AI, advised by Professor Jaegul Choo. My research centers on Vision-Language-Action (VLA) models for robot manipulation.

One question runs through my work: how to ground a model in the spatial structure of a scene. I spent several years localizing sound sources in visual scenes and understanding video, learning to align perception across modalities in space and time. That thread now runs into robotics — predicting the 3D trajectories a robot should follow, and giving policies a robot-centric view of the scene they act in. VLA is where that grounding becomes action.

Alongside this, I work on LLM safety: content moderation for specialized domains and defense for LLM agents.

Research Interests

  • Vision-Language-Action (VLA)
  • Multimodal
  • LLM Safety

News

Publications

2026

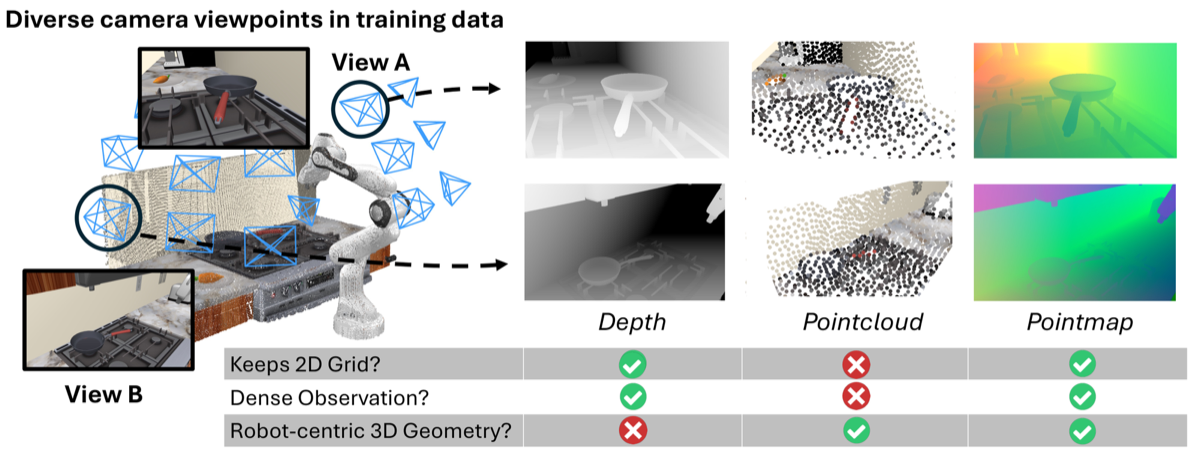
  • Figure for See like a Robot

    See like a Robot: Robot-Centric Pointmaps for Vision-Language-Action Models

    Byungkun Lee, Dongyoon Hwang, Dongjin Kim, Hojoon Lee, Minho Park, Jaegul Choo

    Under Review
    • #VLA
    • #Pointmap
    • #Robot Perception
  • Figure for 3D HAMSTER

    3D HAMSTER: Bridging Planning and Control in Hierarchical Vision Language Action Models through 3D Trajectory Guidance

    Dongyoon Hwang*, Byungkun Lee*, Dongjin Kim*, Hyojin Jang, Hoiyeong Jin, Jueun Mun, Minho Park, Hojoon Lee, Hyunseung Kim, Jaegul Choo (*Equal contribution)

    IROS 2026
    • #VLA
    • #Robot Manipulation
    • #3D Trajectory
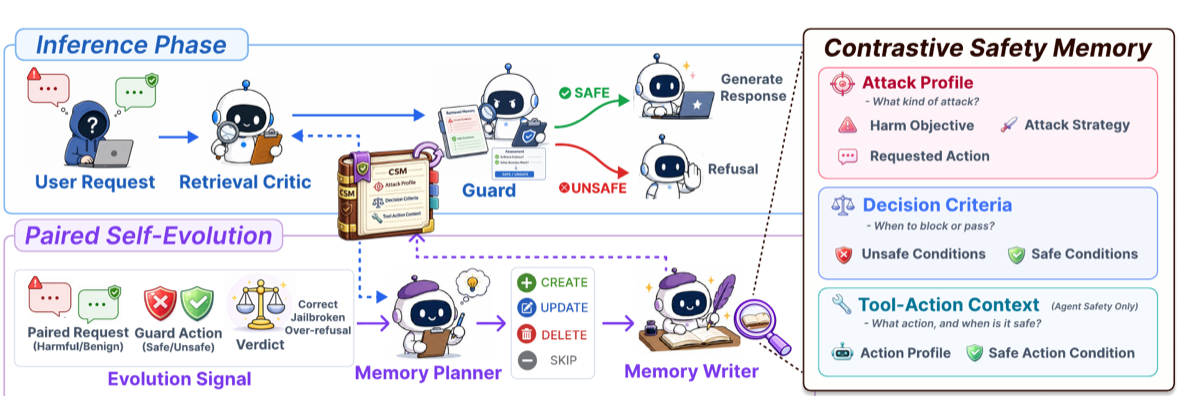
  • Figure for MEMBRANE

    MEMBRANE: A Self-Evolving Contrastive Safety Memory for LLM Agent Defense

    Minseok Choi*, Seungbin Yang*, Dongjin Kim*, Subin Kim, Jungmin Son, Yunseung Lee, Jaegul Choo, Youngjun Kwak (*Equal contribution)

    EMNLP 2026
    • #LLM Safety
    • #Agent Defense
    • #Jailbreak
  • Figure for ExpGuard

    ExpGuard: LLM Content Moderation in Specialized Domains

    Minseok Choi*, Dongjin Kim*, Seungbin Yang, Subin Kim, Youngjun Kwak, Juyoung Oh, Jaegul Choo, Jungmin Son (*Equal contribution)

    ICLR 2026
    • #LLM Safety
    • #Content Moderation
    • #Specialized Domains
  • Figure for LiveWeb-IE

    LiveWeb-IE: A Benchmark For Online Web Information Extraction

    Seungbin Yang, Jihwan Kim, Jaemin Choi, Dongjin Kim, Soyoung Yang, ChaeHun Park, Jaegul Choo

    ICLR 2026
    • #Benchmark
    • #Information Extraction
    • #Web
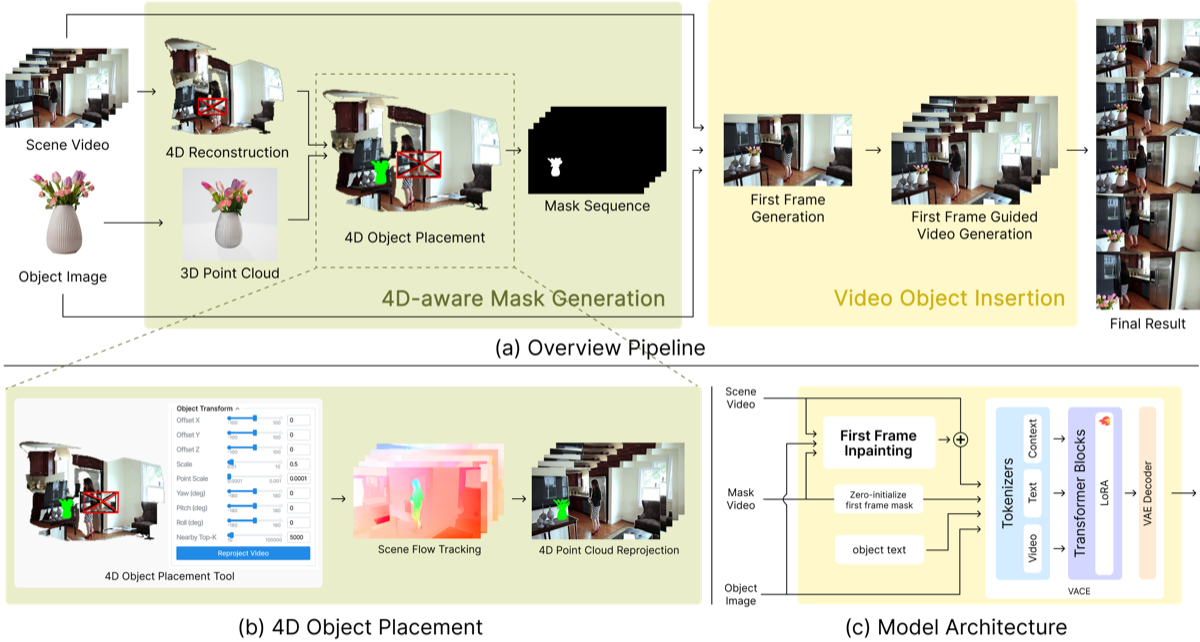
  • Figure for InsertAnywhere

    InsertAnywhere: Geometrically Grounded and Optics-Aware Video Object Insertion

    Hoiyeong Jin, Hyojin Jang, Junha Hyung, Jeongho Kim, Kinam Kim, Dongjin Kim, Huijin Choi, Hyeonji Kim, Jaegul Choo

    ECCV 2026
    • #Video Generation
    • #Diffusion
    • #4D Scene Geometry

2025

  • Figure for Object-aware Sound Source Localization

    Object-aware Sound Source Localization via Audio-Visual Scene Understanding

    Sung Jin Um*, Dongjin Kim*, Sangmin Lee, Jung Uk Kim (*Equal contribution)

    CVPR 2025
    • #Multi-modal
    • #Video Understanding
    • #Sound Source Localization
  • Figure for Watch Video, Catch Keyword

    Watch Video, Catch Keyword: Context-aware Keyword Attention for Moment Retrieval and Highlight Detection

    Sung Jin Um, Dongjin Kim, Sangmin Lee, Jung Uk Kim

    AAAI 2025
    • #Multi-modal
    • #Video Understanding
    • #Moment Retrieval
    • #Highlight Detection
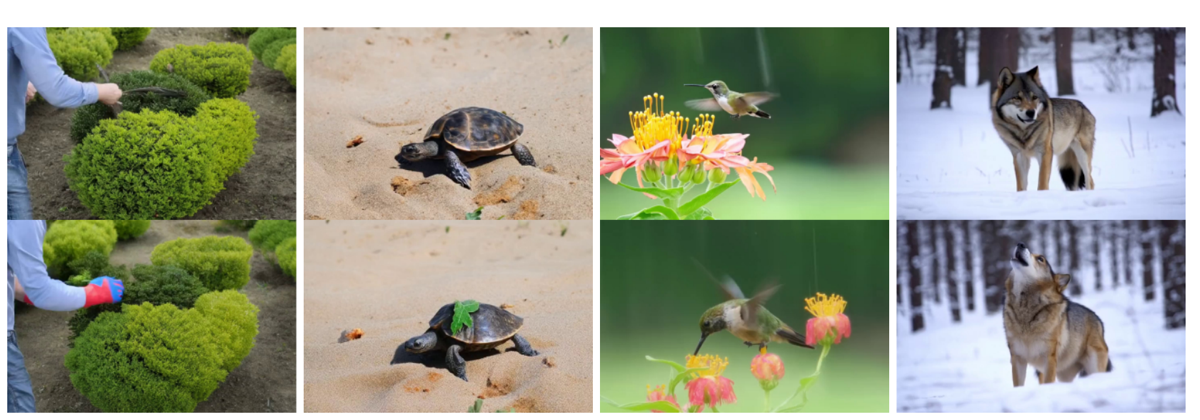
  • Figure for TV-LiVE

    TV-LiVE: Training-Free, Text-Guided Video Editing via Layer Informed Vitality Exploitation

    Min-Jung Kim, Dongjin Kim, Seokju Yun, Jaegul Choo

    arXiv 2025
    • #Video Editing
    • #Diffusion
    • #Training-free

2024

  • Figure for Learning to Visually Localize Sound Sources

    Learning to Visually Localize Sound Sources from Mixtures without Prior Source Knowledge

    Dongjin Kim*, Sung Jin Um*, Sangmin Lee, Jung Uk Kim (*Equal contribution)

    CVPR 2024
    • #Multi-modal
    • #Video Understanding
    • #Sound Source Localization

2023

  • Figure for Audio-Visual Spatial Integration and Recursive Attention

    Audio-Visual Spatial Integration and Recursive Attention for Robust Sound Source Localization

    Sung Jin Um*, Dongjin Kim*, Jung Uk Kim (*Equal contribution)

    ACM MM 2023
    • #Multi-modal
    • #Video Understanding
    • #Sound Source Localization

Education

Experience